One Mistake Game Over
Published: September 7, 2026
Updated: September 15, 2026
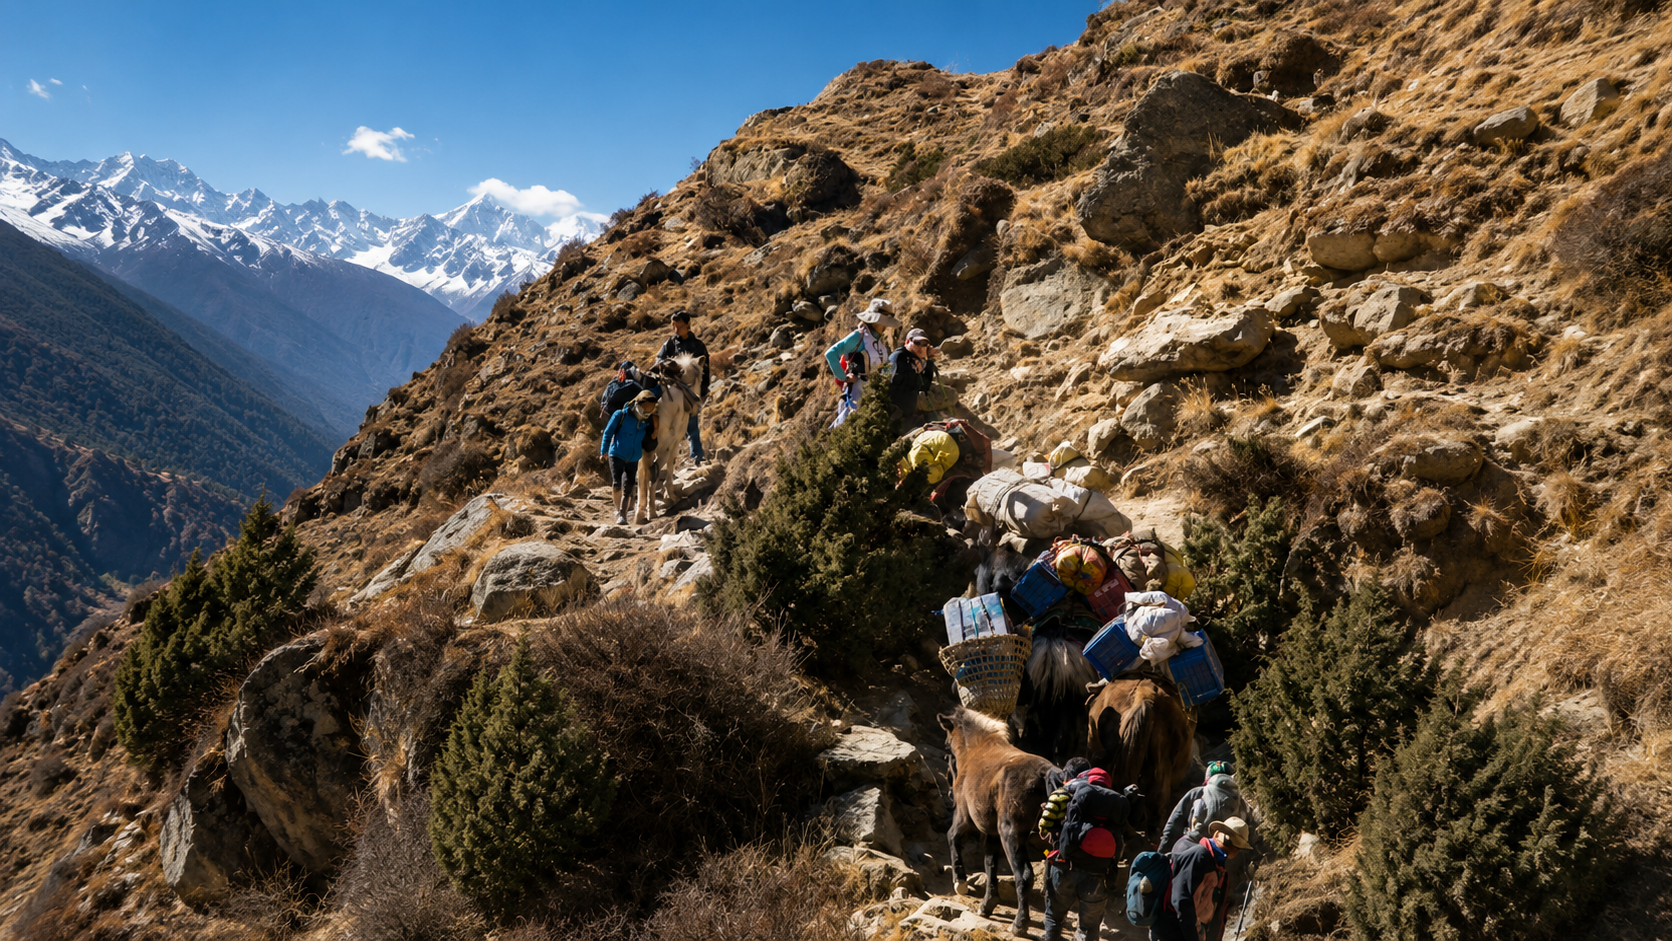
I was on a bus in Nepal several years back, winding through mountain roads. Coming the other direction, another bus, big, moving faster than seemed reasonable. Painted across the front in large letters: ONE MISTAKE GAME OVER.
We saw it on several more buses that afternoon.
I asked someone about it. The driver shrugged. Every bus has one, they said. Sharp curves, no guardrails, a thousand feet down. The sign isn’t decoration. It’s the whole philosophy of the road, written where the oncoming driver can see it.
I think about that sign more than I probably should. As a cyclist, it helps me keep aware that a small lapse in attention can lead to a huge crash. And sometimes there are large drops on mountain roads where it most probably would be “game over”.
Highway Thinking
However, in running XBOSoft, most of what we test doesn’t behave like that bus. Most of it behaves like a highway. Wide shoulders. Room for error. You can misjudge a lane change and just drift back over, no harm done. Software has trained us to think that way. Ship it, see if end users complain about something, fix what breaks. The whole discipline of agile testing assumes you get another lap.
Nassim Taleb wrote a whole book about this kind of thing, back before “black swan” became a phrase people use without knowing where it came from. His point wasn’t really about swans. It was about the difference between risks you can average out over time and risks that show up once, rare and enormous, and rewrite everything that came before them. A highway absorbs a thousand small mistakes and evens out. A mountain road doesn’t average. It just waits. Some refer to that as asymmetric risk. I call it One Mistake Game Over territory.
What AI Changes the Risk
With AI writing more and more code, I wonder if we are still testing for the highway, or did the road change?
I think it’s a compression. AI is good at catching the routine stuff, the null pointer, the off by one, the thing a spell checker for code would have caught anyway. Those defects are shrinking. Good. But the defects that remain are the ones that show up when a model generates code that looks right, passes every test you thought to write, and fails in a way nobody on the team anticipated because nobody on the team wrote the code in the first place. Fewer potholes. Occasional cliff.
The Defects That Look Normal
We saw a version of this with a client last year, a public company, working through an SEC filing after a restatement. The bug wasn’t exotic. It was a rounding assumption buried in reporting, the kind of thing that had passed review a dozen times because it looked like every other line around it. Nobody was careless. Nobody skipped a step. The number just looked like every other number around it, and nothing in the process was built to catch a mistake that looked that normal. That’s what gets you in the end. Not sloppiness. The stuff that looks fine right up until it doesn’t. A rounding error in a multi-currency calculation that ends up being a penny per share.
Testing for the Mountain Road
So what does testing for a mountain road actually look like, if most of our training was for the highway?
I don’t have a clean framework yet. I doubt most people do, this early. But I know it starts with asking a different question about every system we work on. Not “how often does this break,” but “what happens the one time it does.” That’s the whole asymmetry Taleb was writing about. Frequency and consequence aren’t the same thing, and a system can fail rarely and still take you down completely when it does.
What would it take for you or your team to know the difference before the next release, not after?
The XBOSoft Perspective
At XBOSoft, we believe QA needs to look beyond how often software fails and consider what happens when it fails.
Most defects are recoverable. A small number are not. Those high-impact risks deserve more attention, especially as AI generates more code and makes some failures harder to anticipate.
Risk-based testing, domain knowledge, and human judgment help teams identify where one seemingly small defect could have a much larger consequence.
The goal is not to treat every system as high risk. It is to know which parts are.
Next Steps
Before the next release, identify the areas where failure would have the greatest business impact.
Then review whether those areas have enough test coverage, independent validation, edge-case testing, and human review.
The key question is simple:
If this fails only once, how much could it cost us?
Related Articles and Resources
Looking for more insights on Agile, DevOps, and quality practices? Explore our latest articles for practical tips, proven strategies, and real-world lessons from QA teams around the world.